Why activation groups and call stacks matter
IBM i applications can fail in ways that look unrelated: stale data appears, files remain open, or a service job behaves differently after several requests. The underlying issue is often runtime scope. Activation groups determine which resources and program activations share, while the call stack records the active chain of procedure and program calls. Understanding both helps teams isolate faults, choose safer deployment settings, and avoid unnecessary job restarts.
This article explains the relationship in practical terms and provides a review process for RPG, COBOL, CL, and service program workloads.
Activation groups: the runtime container
An activation group is a substructure within an IBM i job. It provides a boundary for activated programs and service programs, static storage, open files, commitment definitions, and other runtime resources. Ending a group can reclaim those resources without ending the entire job. It does not create a separate job or an operating system process.
Default activation group
The traditional default group supports older program models and commands that expect job-level behavior. Use it deliberately, not simply because existing code does.
Named activation group
A named group gives related components a reusable resource boundary. It often suits long-running jobs when controlled sharing and explicit cleanup matter.
New activation group
ACTGRP(*NEW) creates a group for each call and ends it on return, providing isolation. The trade-off is repeated activation cost and no persistent state between calls.
Caller activation group
ACTGRP(*CALLER) places a program in its caller’s group. This can be appropriate for tightly coupled components, but it also expands the effect of leaks and state collisions.
How the call stack fits
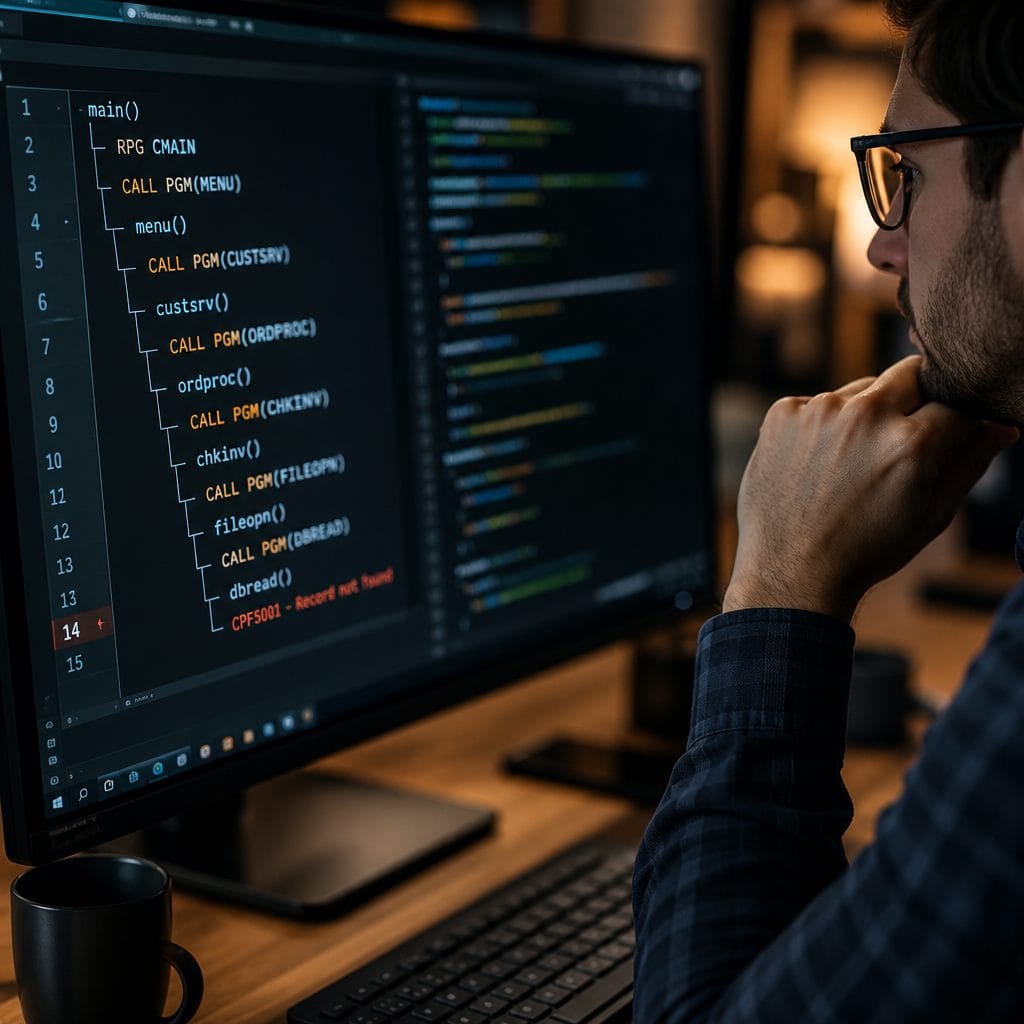
The call stack is ordered by invocation, with the current procedure at the top and earlier callers below it. Each entry provides context such as program or procedure identity, statement location when available, and the route that led to an error. It changes as calls begin and return; an activation group can remain active after individual stack entries disappear.
Example: an interactive request
A display file program calls an order procedure in a service program, which calls a pricing procedure. All three calls may appear on the stack while using one named activation group. When pricing returns, its stack entry vanishes; the service program’s activation and static storage can remain for the next request.
Choose and verify the right model
Treat activation group selection as an architecture decision, not a compiler default. Start with the component’s ownership of state, files, transactions, and failure recovery. Then use this checklist:
- Map entry points. Record commands, menu options, APIs, schedulers, and server jobs that initiate each path.
- Inspect build settings. Review
CRTPGM,CRTSRVPGM, and module binding choices, includingACTGRPvalues and binding directories. - Trace calls. Capture the stack during normal work and failure using job logs, service tools, or the debugger.
- Inventory shared resources. Note static variables, overrides, open files, commitment control, error handlers, and cached objects.
- Test lifecycle events. Exercise first call, repeated call, exception paths, group reclamation, and job end in a nonproduction environment.
For ILE programs, confirm that the chosen setting matches the intended caller relationship. If a service program retains state, document whether that state is scoped per job, per activation group, or per request. Managers should require this explanation before approving runtime changes.
Risks, mistakes, and recovery
The most common mistake is changing ACTGRP to mask a symptom without finding the resource owner. Moving code to *CALLER may expose persistent state; moving it to *NEW may hide a cleanup defect while adding repeated initialization. Another mistake is assuming RCLRSC clears every ILE resource. Its effect depends on program model and call context, so verify behavior rather than treating it as universal recovery.
Recover methodically: preserve the job log, note the stack and message identifiers, reproduce safely, then correct ownership or cleanup logic. Restart the affected job only when business impact requires it or when controlled reclamation cannot restore a known state.
A simple decision framework
Choose isolation when failures or state must not cross request boundaries; choose a named group when components intentionally share resources across calls; use *CALLER only when the caller owns that lifecycle. Your next step is: select a job, map its stack and activation groups, then test cleanup and repeated calls before safely changing production.